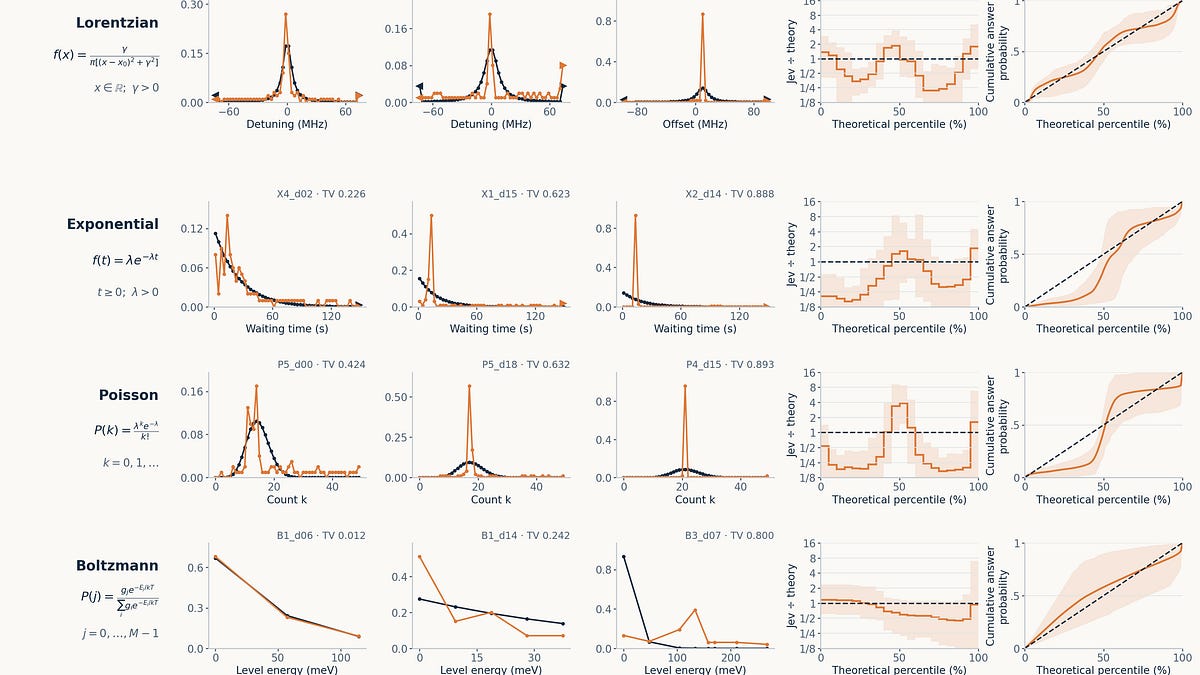
In this analogy, Large Language Models (LLMs) like Claude or GPT are System Two models and “Decision Models” like Jev and its predecessors (e.g. Laya) are System One.
The transformer architecture is the backbone of modern LLMs, and it is an extremely flexible, general paradigm for learning most tasks. However, modern LLMs are irreducibly stochastic, autoregressive, and their output style (freeform text) is not well suited to classification tasks. For example, let’s say I made a call to an LLM, something like claude(“2 + 2 = ?”)? We expect 4, but as a string, an integer, a float…? With Jev, you would instead call something like jev("2+2=?", "3 : int, 4 : int, 5 : int") , and you’d receive 4, correctly typed as an integer.